dsh-tool-accurate-vision
Model-facing accurate_vision tool: precise image spatial reasoning via a vision model
imkingjh999
@imkingjh999
⬇ 1
★ 0
main
安装
dsh plugin --profile web add github:imkingjh999/dsh-tool-accurate-vision
需要可复现安装时,可在仓库后追加 #commit 固定提交。
Model-facing accurate_vision tool: precise image spatial reasoning via a vision model
该插件未提供要点说明,请参考仓库 README。
bounding-boxdshdsh-pluginvision
- 安装并启动 DeepSeek Harness:
npx @deepseek-ai/dsh web - 在终端执行上面的安装命令(CLI 会解析插件并核验来源)
- 用 dsh plugins list 确认已安装,必要时重启 Harness 生效
插件以当前 dsh 进程的权限运行,安装时可能执行代码。请先通读仓库源码与许可证,确认无破坏性命令与越权访问;本站只做索引,不对第三方插件安全性作担保。
| 代码仓库 | github.com/imkingjh999/dsh-tool-accurate-vision |
| 许可证 | MIT |
| 主要语言 | main |
| 下载量 | 1 |
| GitHub 星标 | 0 |
| 最近推送 | 2026-08-17 |
| 收录日期 | 2026-09-19 |
| 分类 | 工具与能力 |
事实信息来自公开插件目录快照(2026-10-03),介绍文案由本站再加工。
以下为插件仓库 README 全文(原始内容,由公开目录抓取整理)。
# dsh-tool-accurate-vision
[](https://awesome-dsh-plugin.com)
Model-facing `accurate_vision` tool for
[DeepSeek Harness](https://github.com/deepseek-ai/deepseek-harness):
precise spatial reasoning over an image file via an OpenAI-compatible vision model.
Ported from [`pi-accurate-vision`](https://github.com/imkingjh999/pi-accurate-vision).
A vision model reads the image and returns a structured note plus
**bounding-box primitives normalised to 0–1000**; this tool formats them as a
`` block the next model turn reads — giving a text-only agent
exact object positions, layout, and OCR without losing spatial fidelity.
English | [中文](README.zh.md)
## Install
```sh
dsh plugin --profile web add dsh-tool-accurate-vision
```
Or from source:
```sh
dsh plugin --profile web add github:your-username/dsh-tool-accurate-vision
```
Set the vision API key (separate from `DEEPSEEK_API_KEY`):
```sh
export VISION_API_KEY=sk-...
```
## How it works
```
image file ──► base64 data URL ──► vision chat/completions ──► JSON note + primitives
│
XML ──► next model turn
```
The pure vision core ([`src/bridge.ts`](src/bridge.ts)) is provider-agnostic:
any OpenAI-compatible multimodal `chat/completions` endpoint works.
The Cordis host ([`src/index.ts`](src/index.ts)) owns config, credential
resolution, and the registered tool.
Every call also writes a self-contained SVG — the original image with every
bounding box and label drawn on it — returned as the `annotatedImage` path,
so the boxes can be eyeballed instead of trusted blind
(set `annotate: false` to skip it).
## Case study: rigorous distance computation
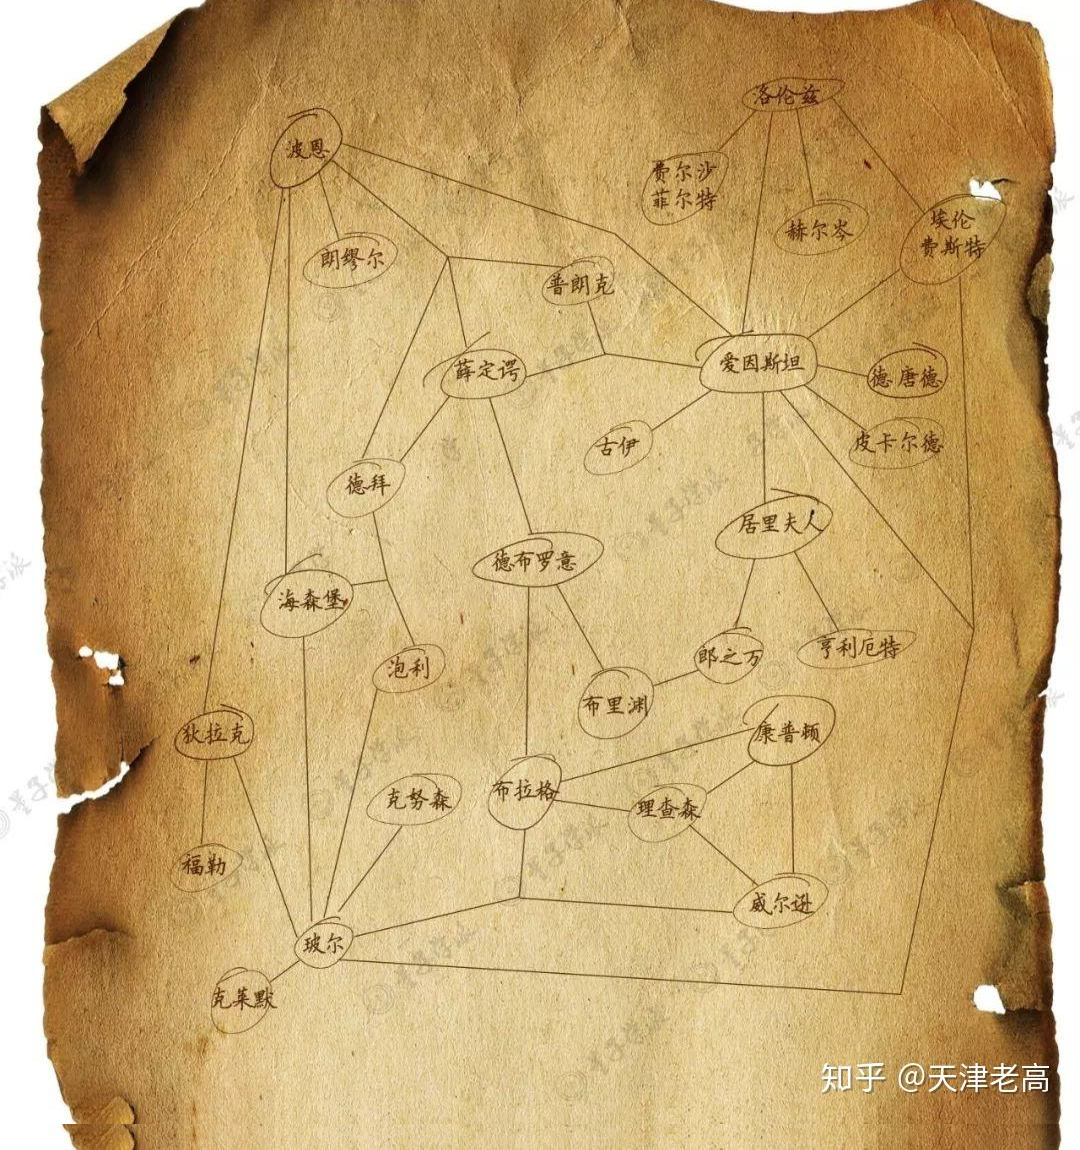
Ask an image question with a checkable answer — *in this hand-drawn physicists
network, which node sits physically closest to 居里夫人 (Marie Curie), ignoring
the connecting lines?* — and the gap between plain vision and this tool becomes
measurable. The test image is the aged network diagram below:
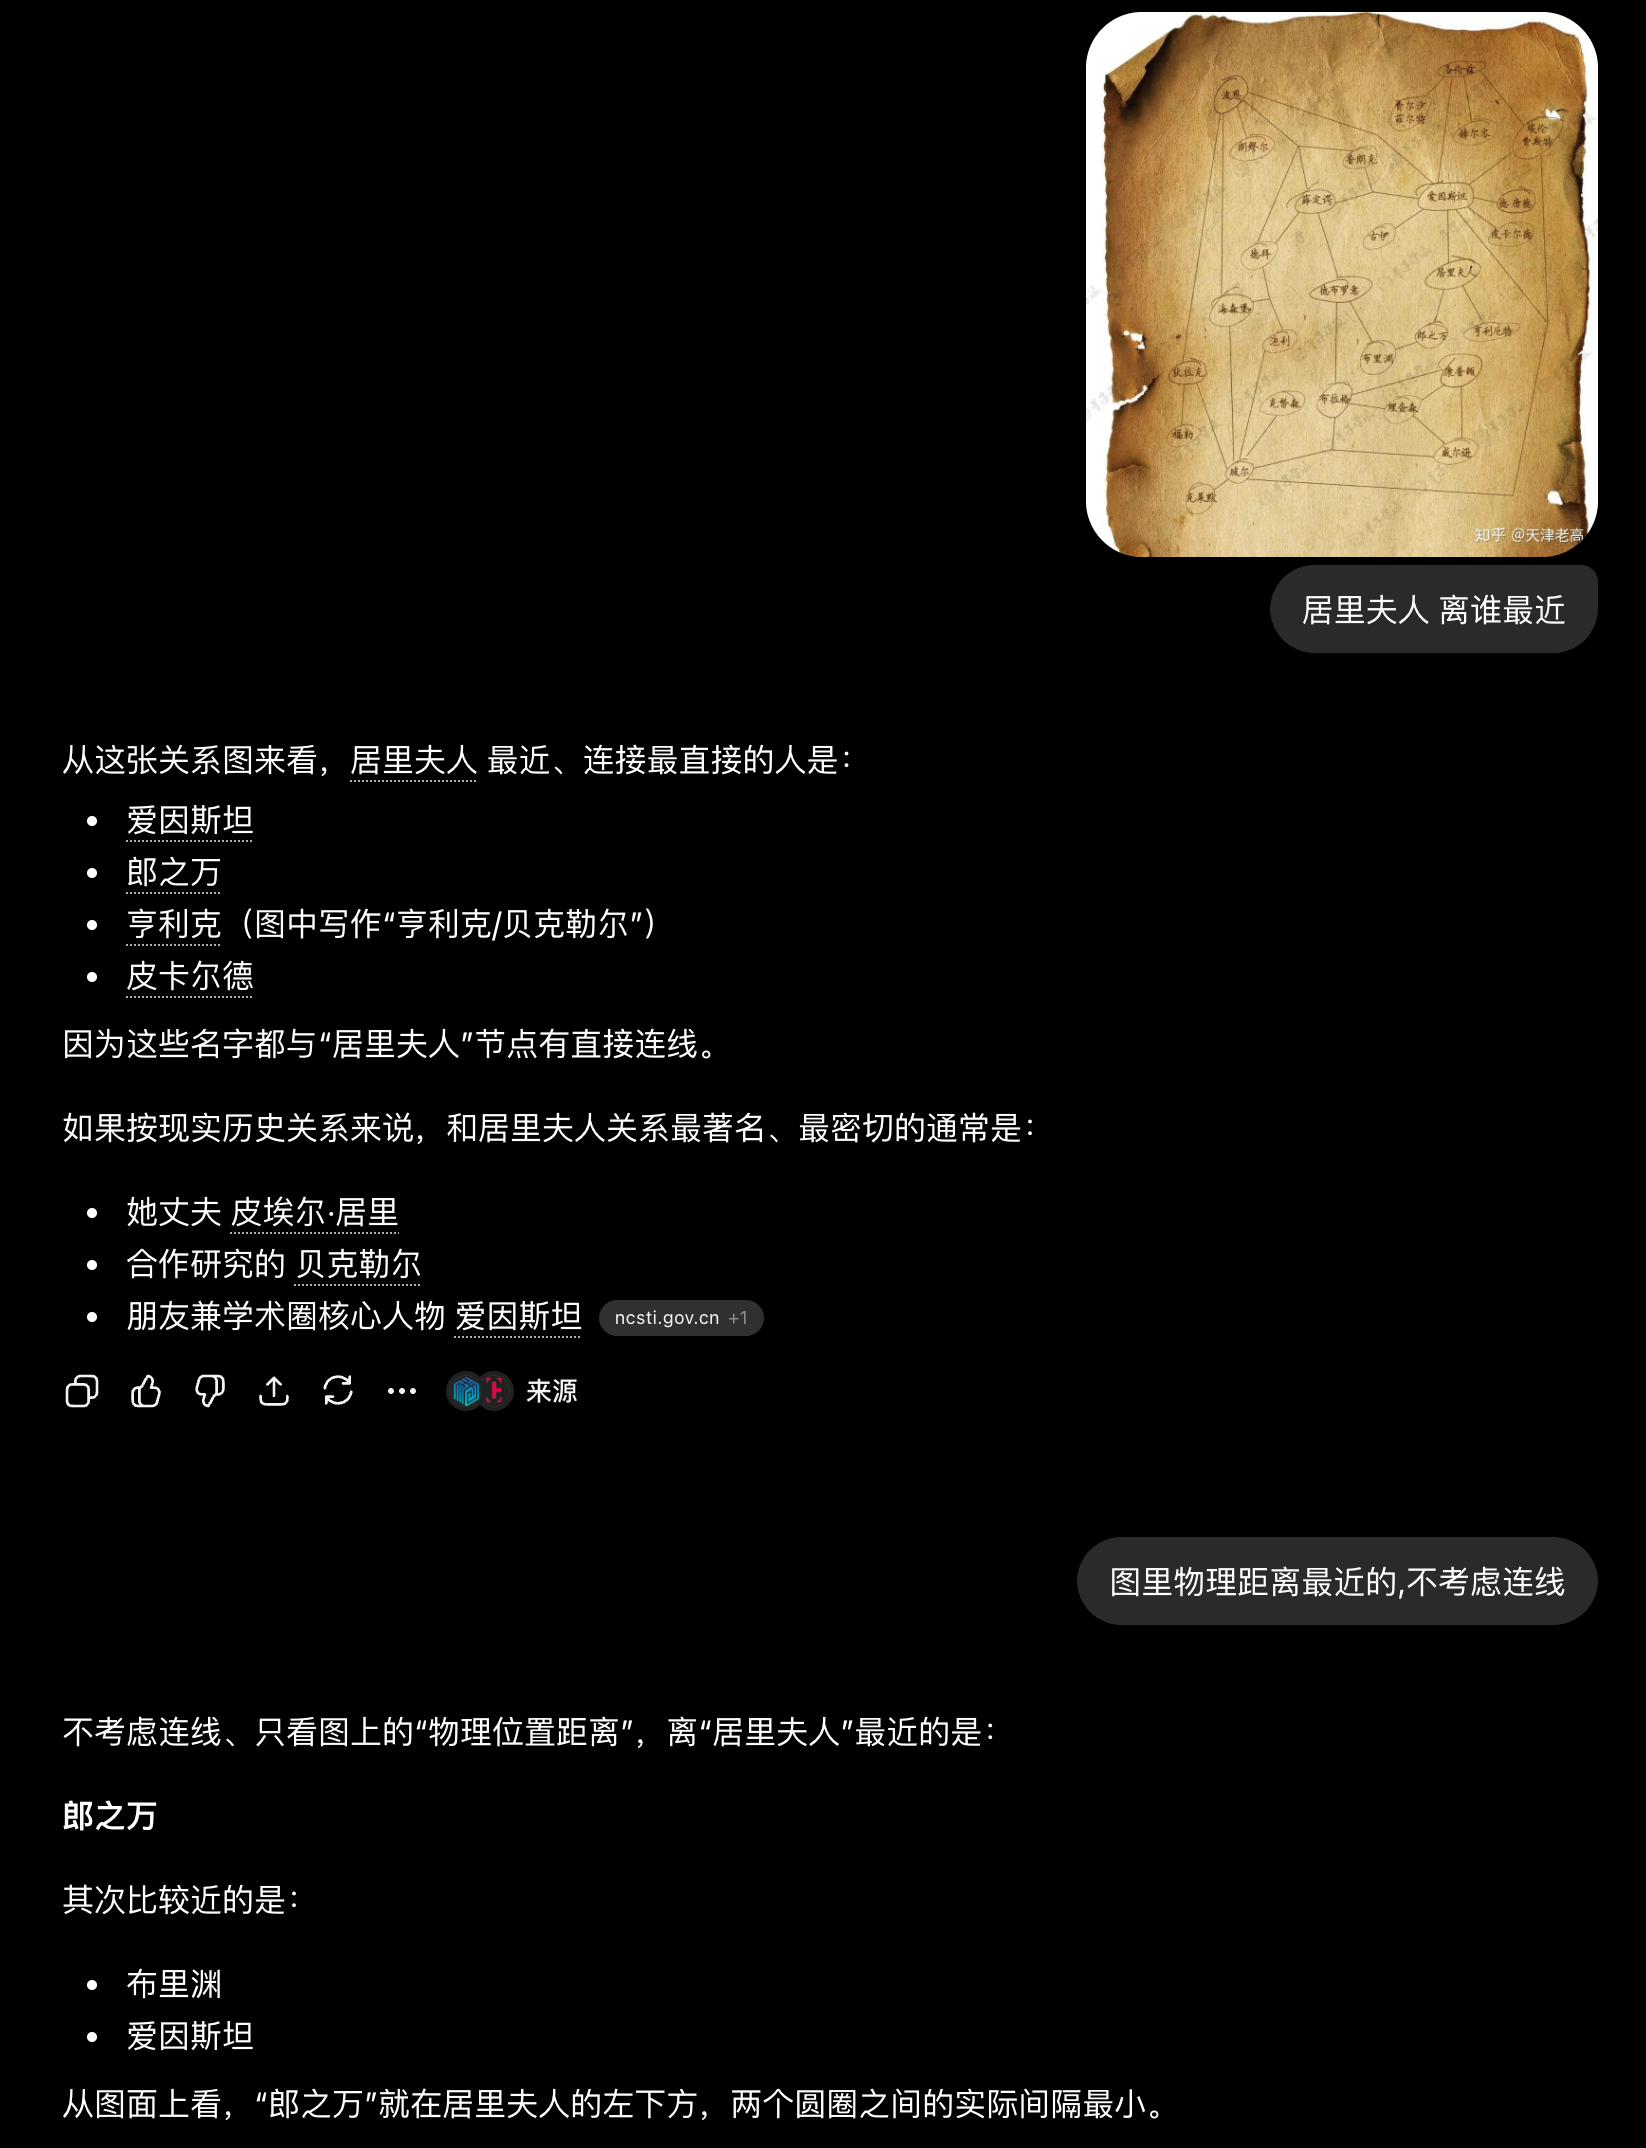
1. **Asking a multimodal model directly** yields a visual impression, not a
measurement: "郎之万, at the lower left, looks closest" — nothing to verify,
and as it turns out, wrong.
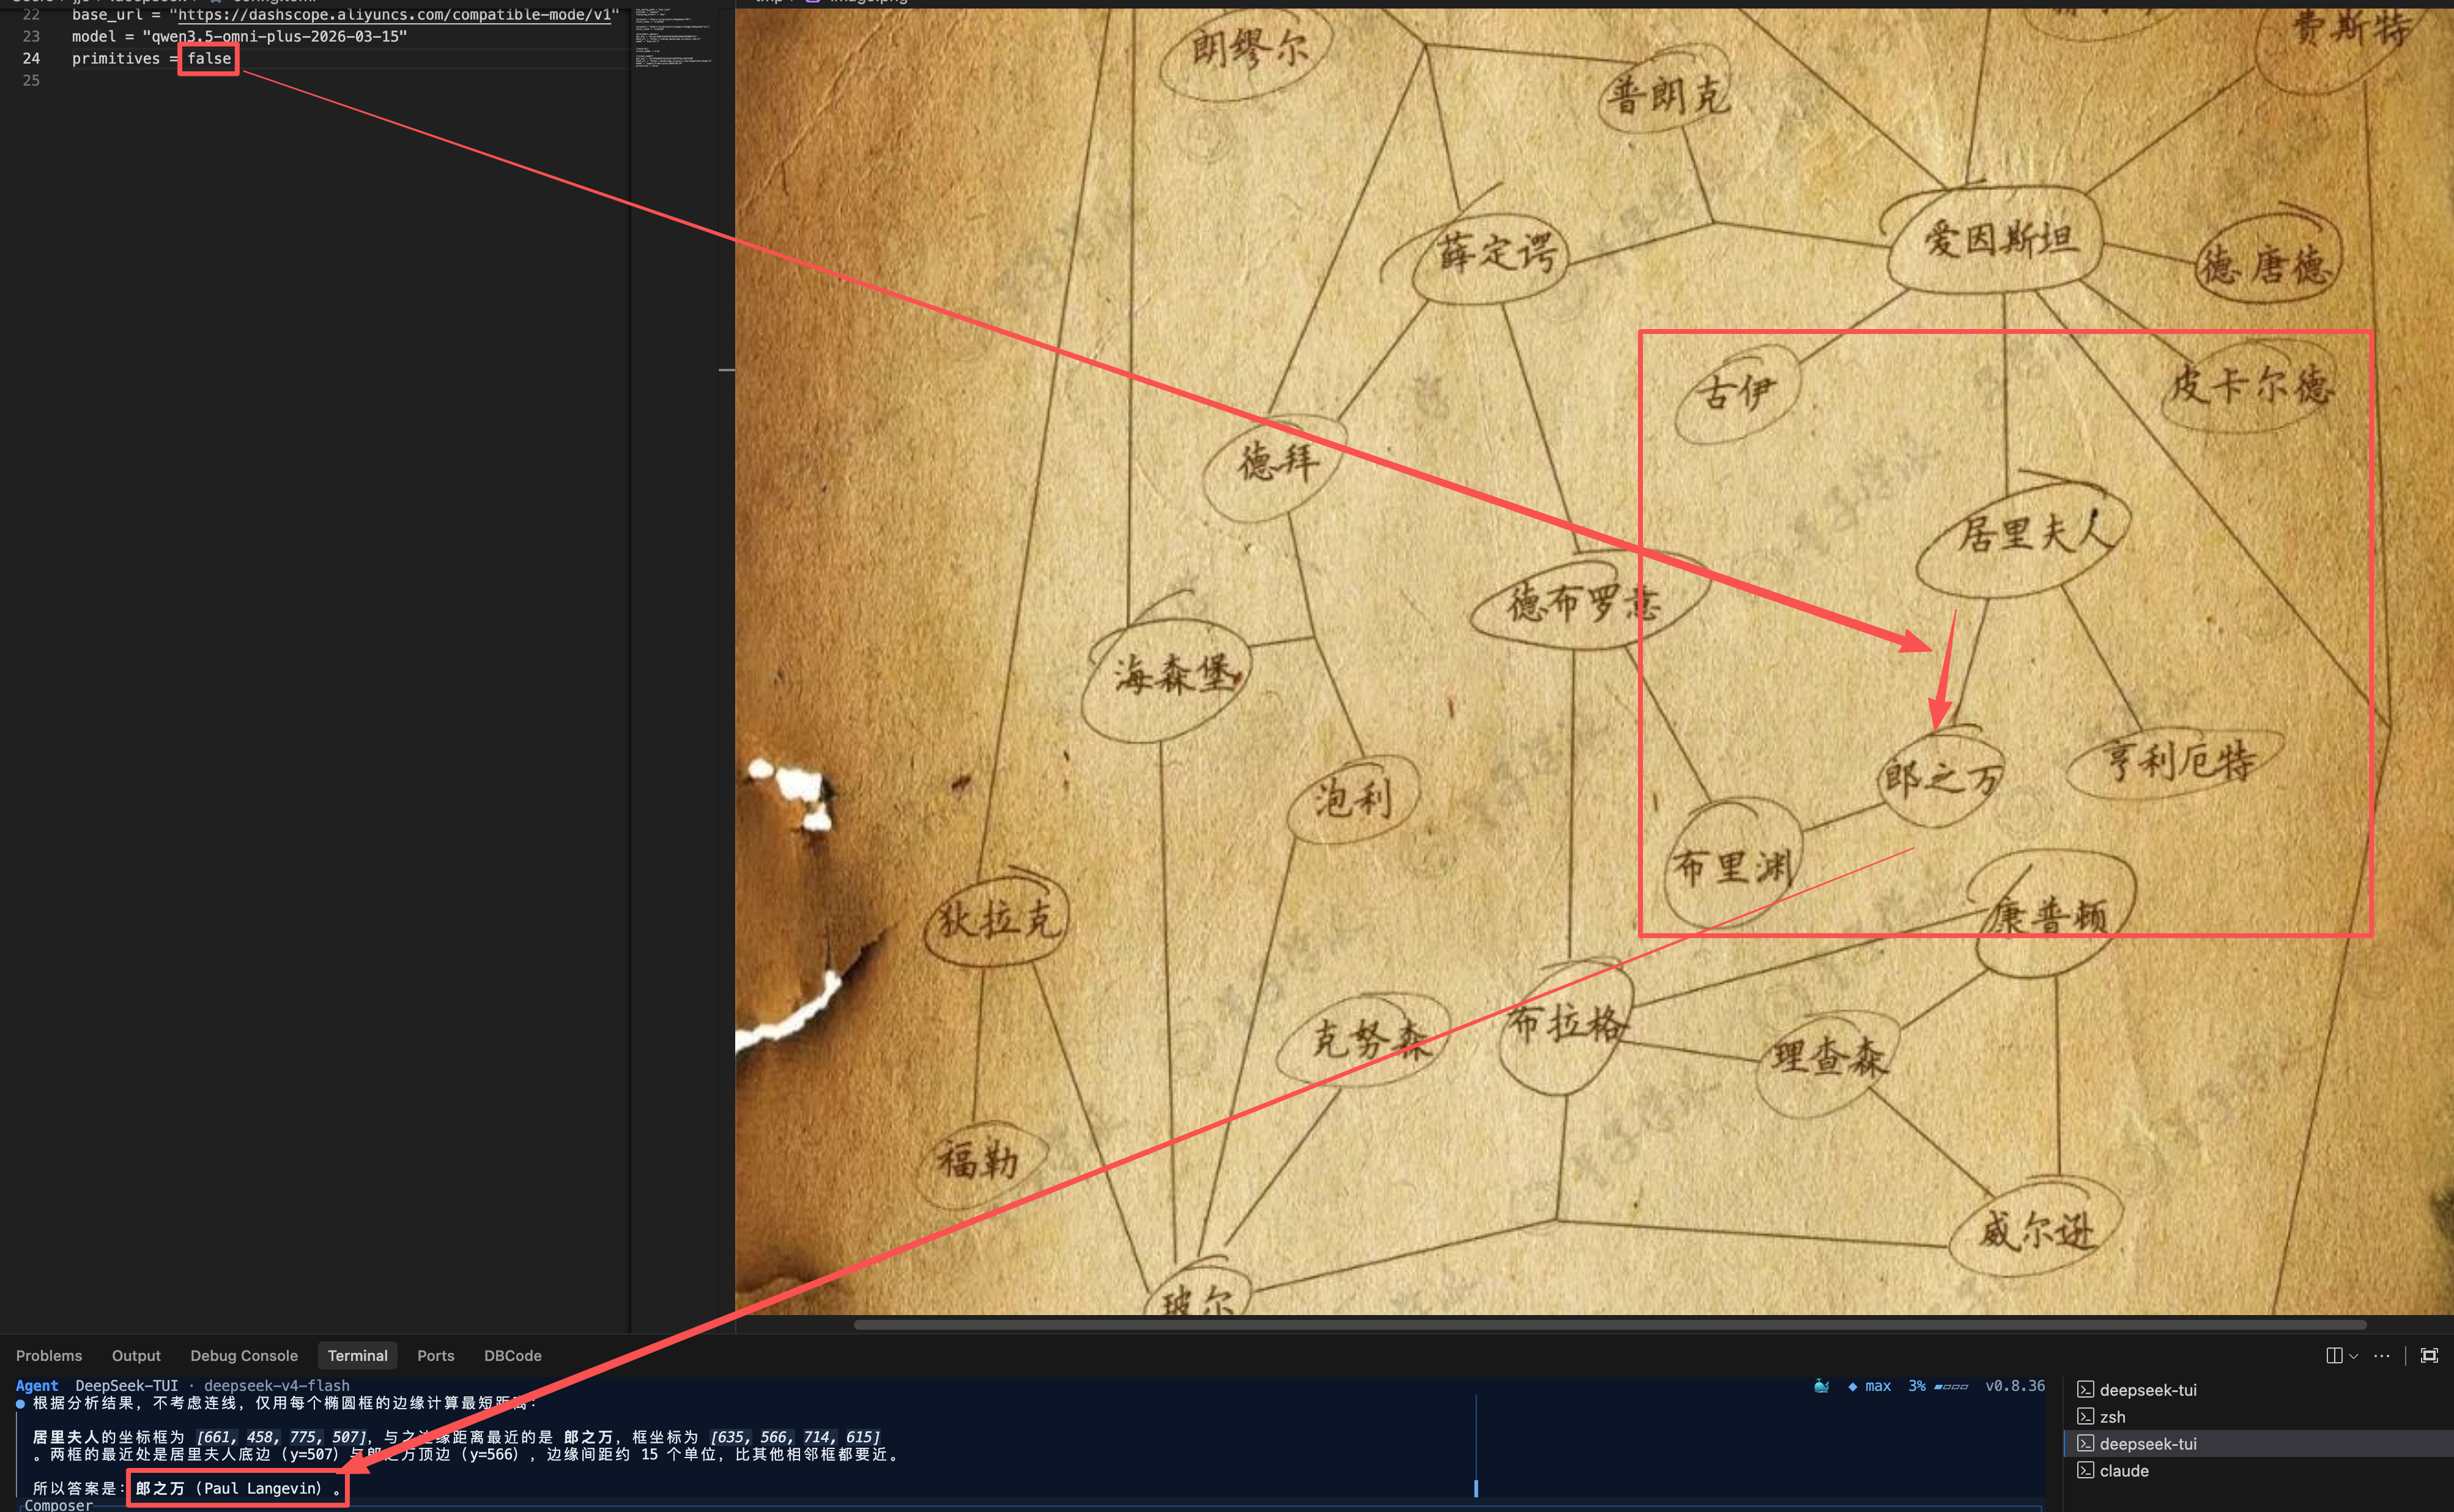
2. **Vision text without structured primitives** can be worse than no numbers
at all: the model invents plausible-looking coordinates in prose, then
contradicts itself — a claimed ~15-unit gap while its own two boxes imply
59 — and returns the same wrong answer.
3. **With this tool's normalised primitives**, every node carries a checkable
0–1000 bounding box, so the agent computes real edge-to-edge distances in
code: 皮卡尔德 25.96 vs 郎之万 58.00. The correct answer — 皮卡尔德
(Piccard) — arrives with the numbers that prove it.
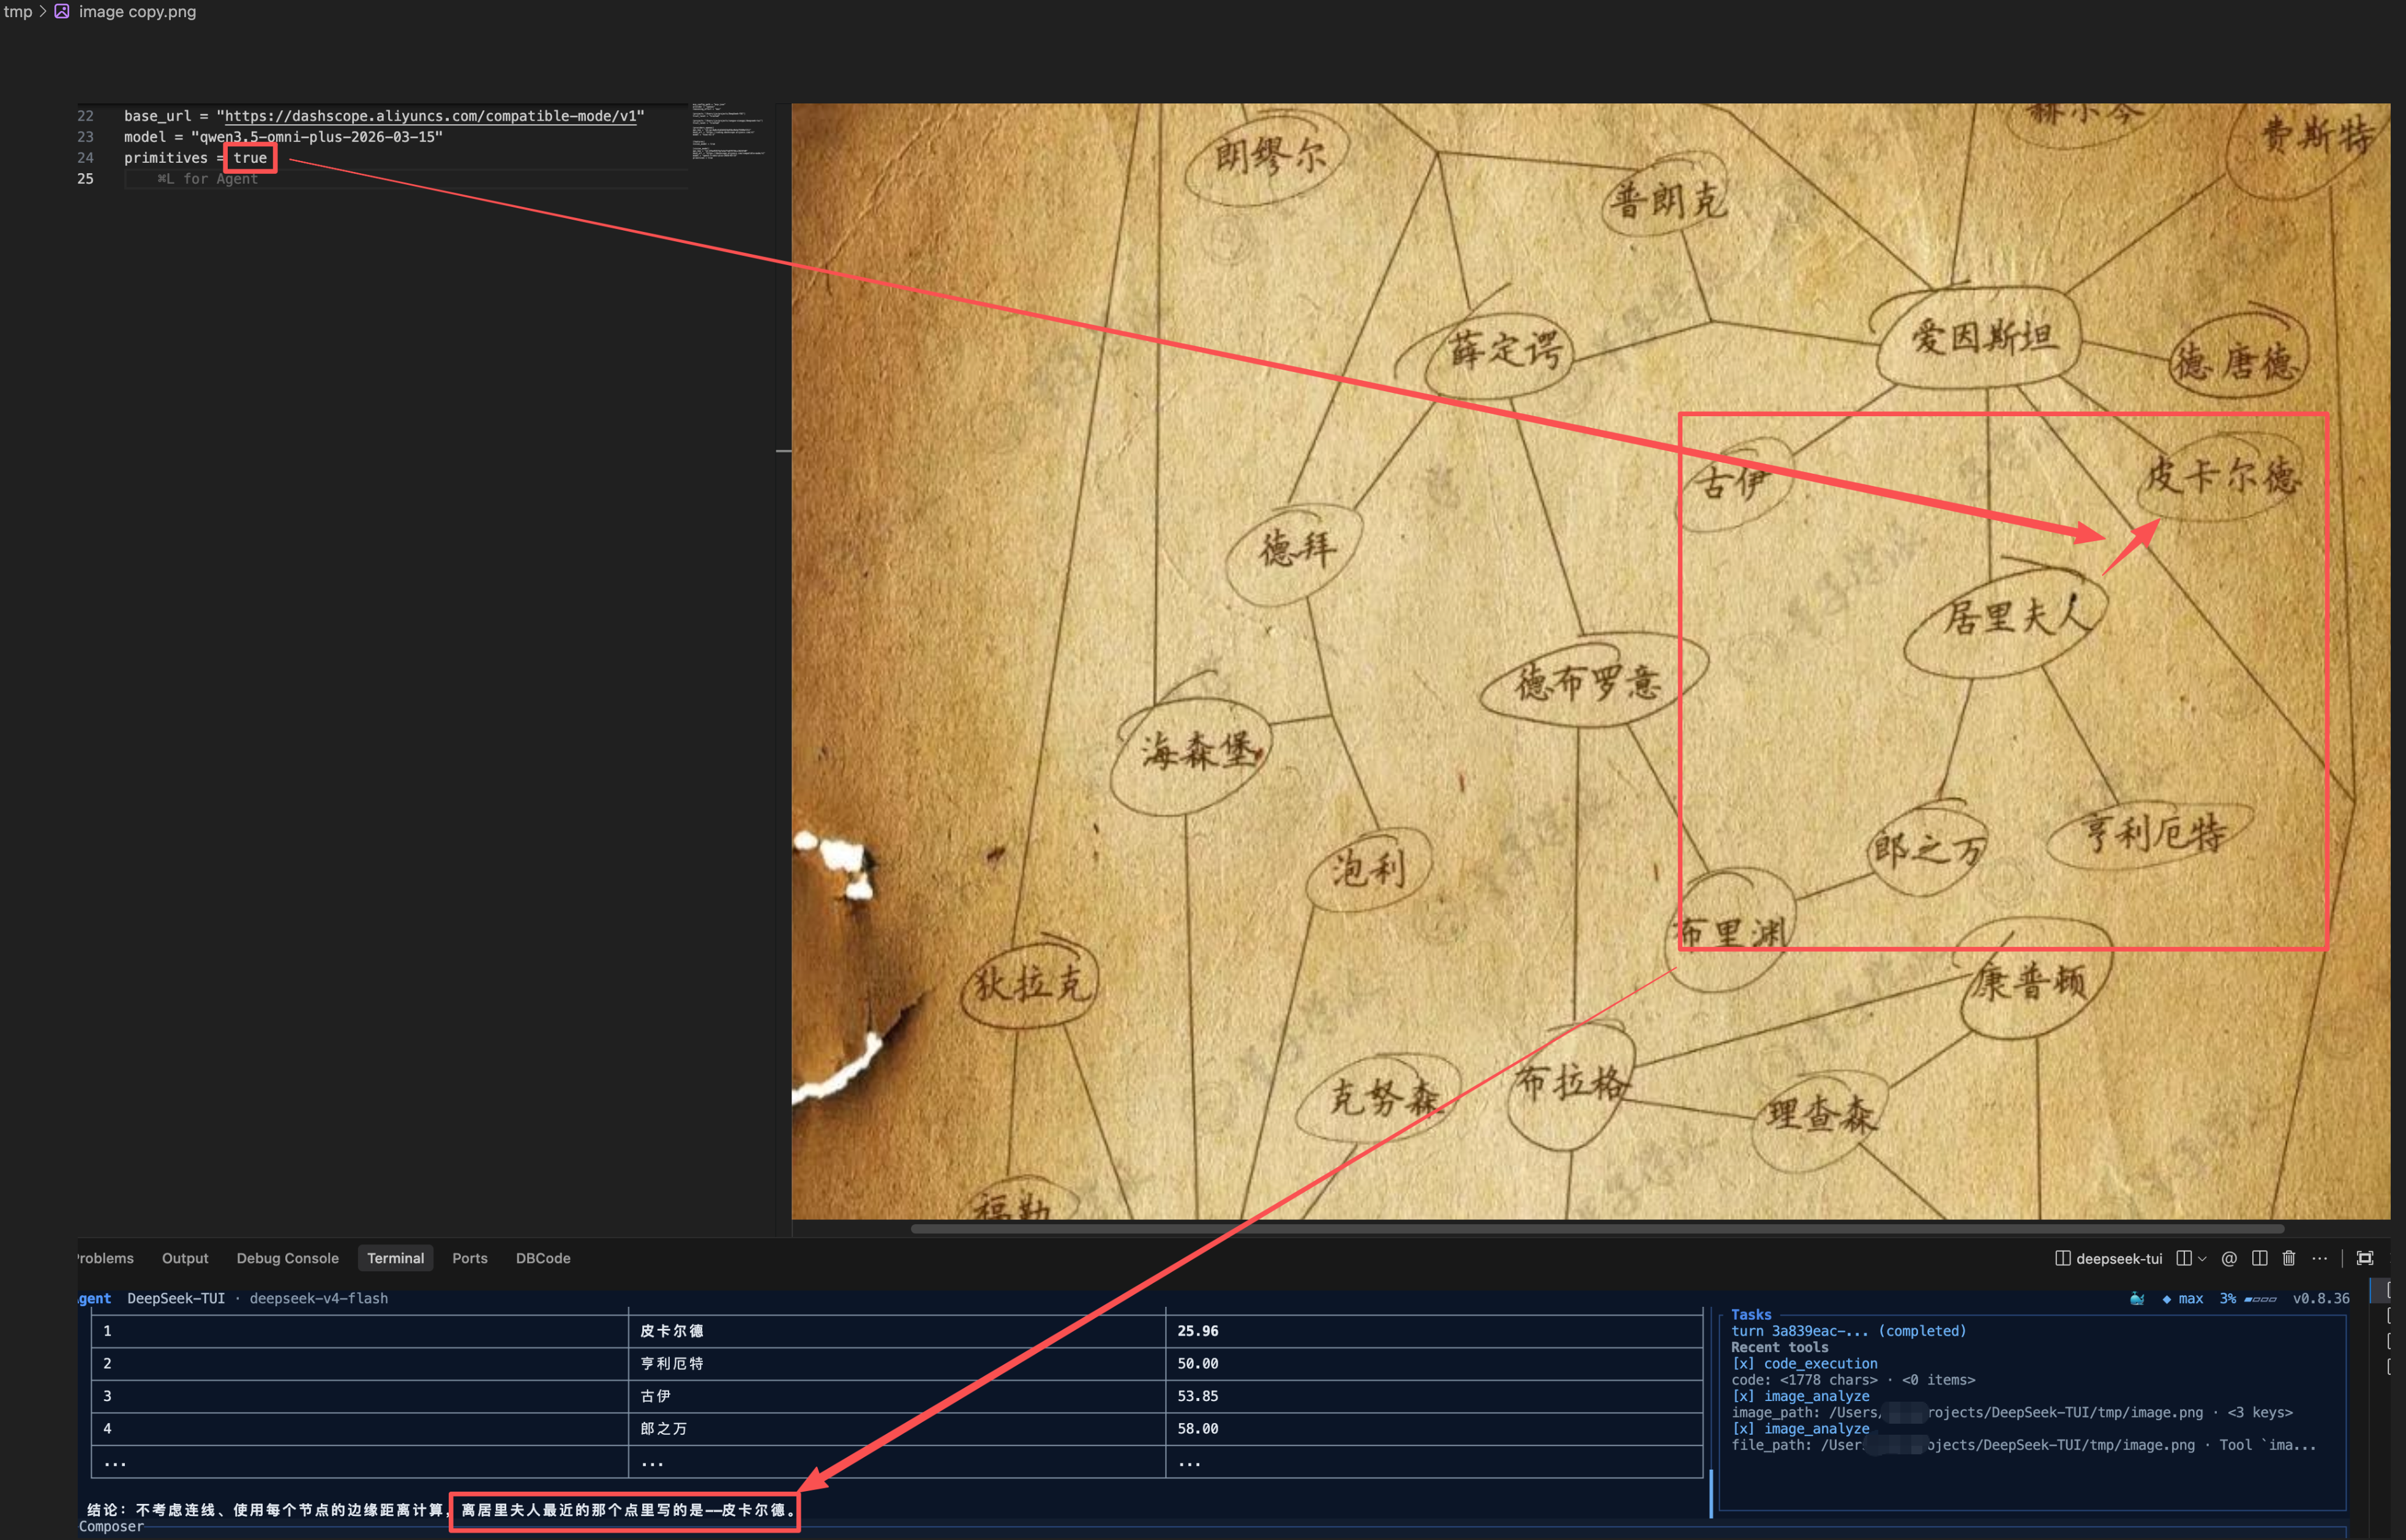
That is the core advantage: bounding-box primitives turn visual impressions
into geometry. Positions, distances, and layout become facts a text-only agent
can compute and verify, not guesses it has to trust. For distance questions the
canonical edge-to-edge computation pairs the *facing* edges per axis
(`dx = max(a.x1 - b.x2, b.x1 - a.x2, 0)`, same for y, then `hypot`); the
tested helper `bboxEdgeDistance(a, b)` ships with this package so downstream
agents never pair the wrong edges.
## Configuration
Override in your profile's `cordis.patch.yml`:
```yaml
- id: tool-accurate-vision
config:
model: gpt-4o # any OpenAI-compatible multimodal model
baseURL: https://api.openai.com/v1
apiKeyEnv: VISION_API_KEY # credential reference
primitives: true # request bounding-box primitives
annotate: true # also write an SVG with boxes drawn on the image
maxTokens: 8192
timeoutSecs: 120
temperature: 0
disableThinking: true # skip the reasoning phase (MiniMax): faster & steadier
```
## Origin
Faithful port of `pi-accurate-vision` (which itself extracted DeepSeek-TUI's
`crates/tui/src/vision/bridge.rs`). The parsing, prompt, and formatting logic
is preserved verbatim; only the host integration targets the Cordis `ctx.tools`
registry with schemastery config and the credentials seam.
## License
MIT
数据来源:公开的 DeepSeek Harness 插件目录与各插件 GitHub 仓库。本站为独立第三方目录,与 DeepSeek、幻方(High-Flyer)及插件作者均无隶属或背书关系。

